Greg Tutt
Chief Technology Officer, Strato
There is an expectation I hear quite often when discussing AI with customers.
We are getting used to AI feeling almost human. We can ask a question in natural language, provide very little context, and still get an answer that feels remarkably intelligent.
So when we bring AI into enterprise systems, it is easy to assume the same thing: give it access to the information and it should be able to work the rest out.
Some of the most interesting problems I’ve seen emerge when AI starts working with what is already there.
When the categories aren’t actually clear
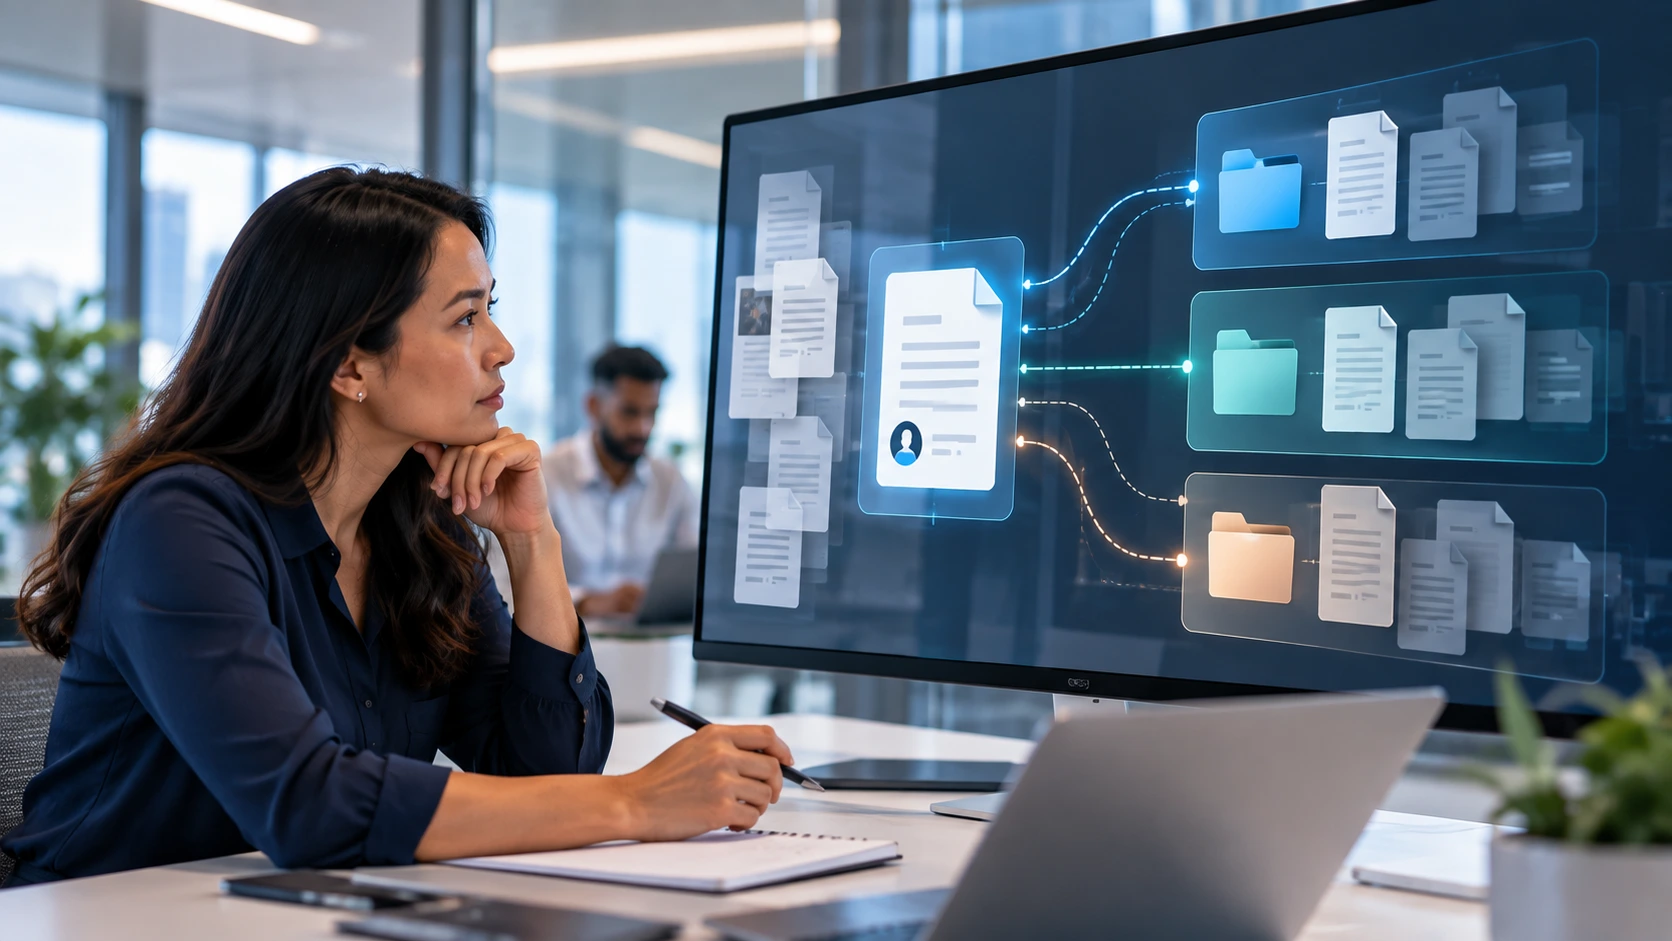
I recently had discussions with customers about using AI to automatically classify HR documents.
The expectation sounded reasonable: take an incoming document, understand its contents, and determine with a high degree of confidence which category it belongs to.
Once we started testing the requirement, the problem turned out to be the categories themselves. Some of the categories were very similar. In certain cases, the same document could reasonably belong to more than one. And when we asked what rules a person should use to distinguish between them, there wasn’t always a clear answer.
The AI wasn’t necessarily struggling to understand the document. It was being asked to infer an operational rule that had never really been formalised.
A person doing the same job might simply make a judgement call based on experience. Someone else might make a slightly different one. Over time, those decisions can become part of the way the organisation operates without anyone necessarily noticing the inconsistency. Once you ask AI to apply the rule consistently, that ambiguity becomes obvious.
The organisation was effectively asking AI to make a consistent decision about something that hadn’t yet been consistently defined by people.
AI can also expose what we’ve stopped noticing
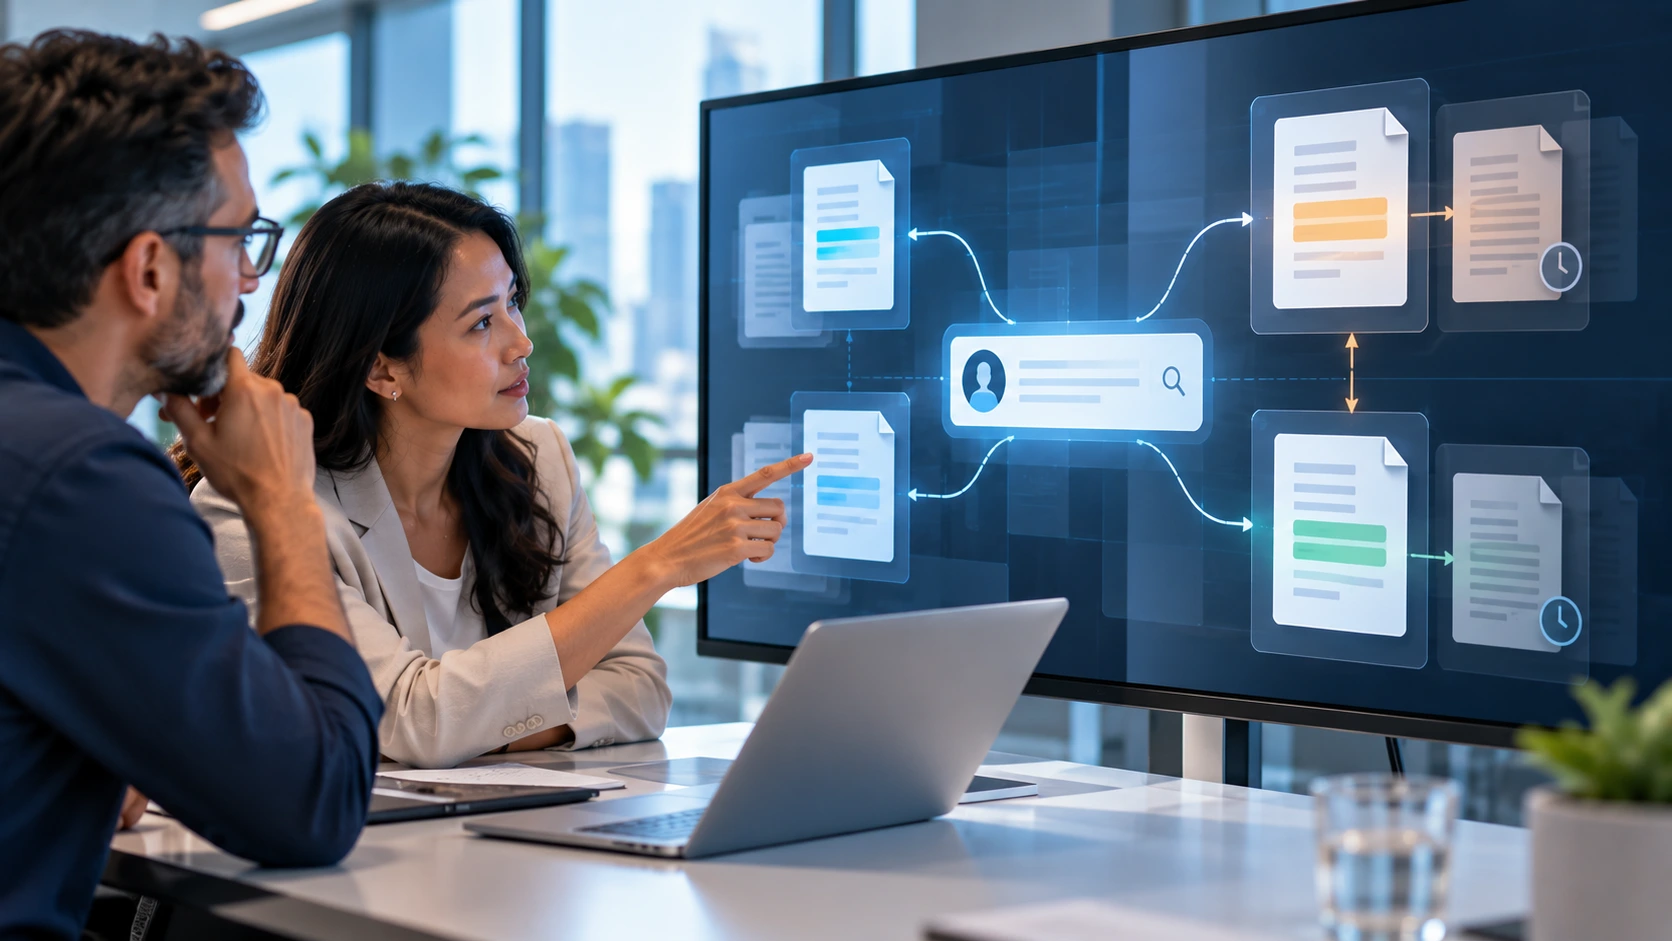
The same issue comes up with HR policies. Policy questions seem like a natural use case for generative AI: give the AI access to the relevant policies and let employees ask questions conversationally rather than searching through documents.
It can work remarkably well, but the reliability of the answer still depends heavily on the quality, currency and governance of the information behind it.
In one case, we discovered that two policies contained contradictory information. We only found it because the AI surfaced both versions.
We have also encountered outdated policies that were still available alongside current ones. From the AI’s perspective, both were sources of information. Unless there is enough context to determine which source is current and authoritative, an apparently simple question becomes much harder to answer reliably.
What looked like an AI issue was really a document governance issue that had already been there.
People are surprisingly good at working around process debt
One thing I think we talk about less is what AI exposes in the way organisations already operate.
Organisations accumulate technical debt over time, and we generally know what that looks like: old code, ageing integrations, workarounds and systems that become increasingly difficult to maintain.
The same thing happens with processes. Policies begin to overlap, categories evolve, exceptions become part of normal operations, ownership becomes less clear, and old documents remain accessible alongside current ones.
Experienced employees learn how to work around that ambiguity. They know which policy is out of date, which two categories effectively mean the same thing, or when the documented process is not quite how a particular situation is handled in practice.
A lot of that knowledge lives in people’s heads rather than in the process, and experienced people get very good at working around the ambiguity. AI can make that ambiguity more visible because it has to work from the information, definitions and rules it has been given.
AI as an operational stress test
In both examples, AI is running into decisions the organisation has never fully formalised. That might mean deciding which category a document belongs to, which policy is authoritative, how an exception should be handled, or who owns the decision when the answer is unclear.
People usually work those things out from experience and context. AI does not have years of organisational context to fall back on, so the missing rules become much more obvious.
We spend a lot of time talking about whether technology is ready for AI. I think there is another question worth asking:
Are our processes and information ready for AI?
If we want an AI system to classify documents consistently, we first need to know what those classifications actually mean.
If we want it to answer policy questions reliably, we need clarity around which policies are current, where they apply, and what happens when they conflict.
If we want AI to take on more complex HR processes, those same questions become even more important. Ownership, permissions, approvals, exceptions and sources of truth all need to be understood. Improving those areas also improves the underlying operation, whether AI is involved or not.
One of the more useful effects of AI may turn out to have less to do with automation than we expect. It may be showing organisations where people have been compensating for unclear rules, outdated information and inconsistent processes for years.